Haiyang Xu

USTC
B.S.
2020 - 2024
UC San Diego
Ph.D. student
2024 - Present

I am a third-year Ph.D. student at UCSD, advised by Dr. Zhuowen Tu. My current research focus is on generative models, especially on topics such as controllable generation and video generation.

Previously, I was a Research Intern at Adobe in 2025 Summer, working with Dr. Zhaowen Wang, Dr. Li-Yi Wei, Dr. Nanxuan Zhao and Dr. Cuong Nguyen; at NYU Courant in 2024 Fall, working with Dr. Saining Xie; and at Baidu in 2022 Summer, working with Dr. Dongliang He, Dr. Zhichao Zhou, and Dr. Jingdong Wang. During my undergraduate, I was fortunate to work with Dr. Xiangnan He and Dr. Shuo Wang.

alternative

Experience

USTC
Research Intern
Jan 2022 - Jun 2023
Advised by: Dr. Xiangnan He and Dr. Shuo Wang
Baidu
Research Intern
Jul 2022 - Nov 2022
Advised by: Dr. Dongliang He and Dr. Jingdong Wang
UC San Diego
Research Intern
Jul 2023 - Nov 2023
Advised by: Dr. Zhuowen Tu
NYU Courant
Research Intern
Jan 2024 - Nov 2024
Advised by: Dr. Saining Xie
Adobe
Research Intern
Jun 2025 - Nov 2025
Advised by: Dr. Zhaowen Wang, Dr. Li-Yi Wei, Dr. Nanxuan Zhao and Dr. Cuong Nguyen
Adobe
Research Intern
Jun 2026 - Present
Advised by: Dr. Mingze Xu and Dr. Yuanjun Xiong

Latest News

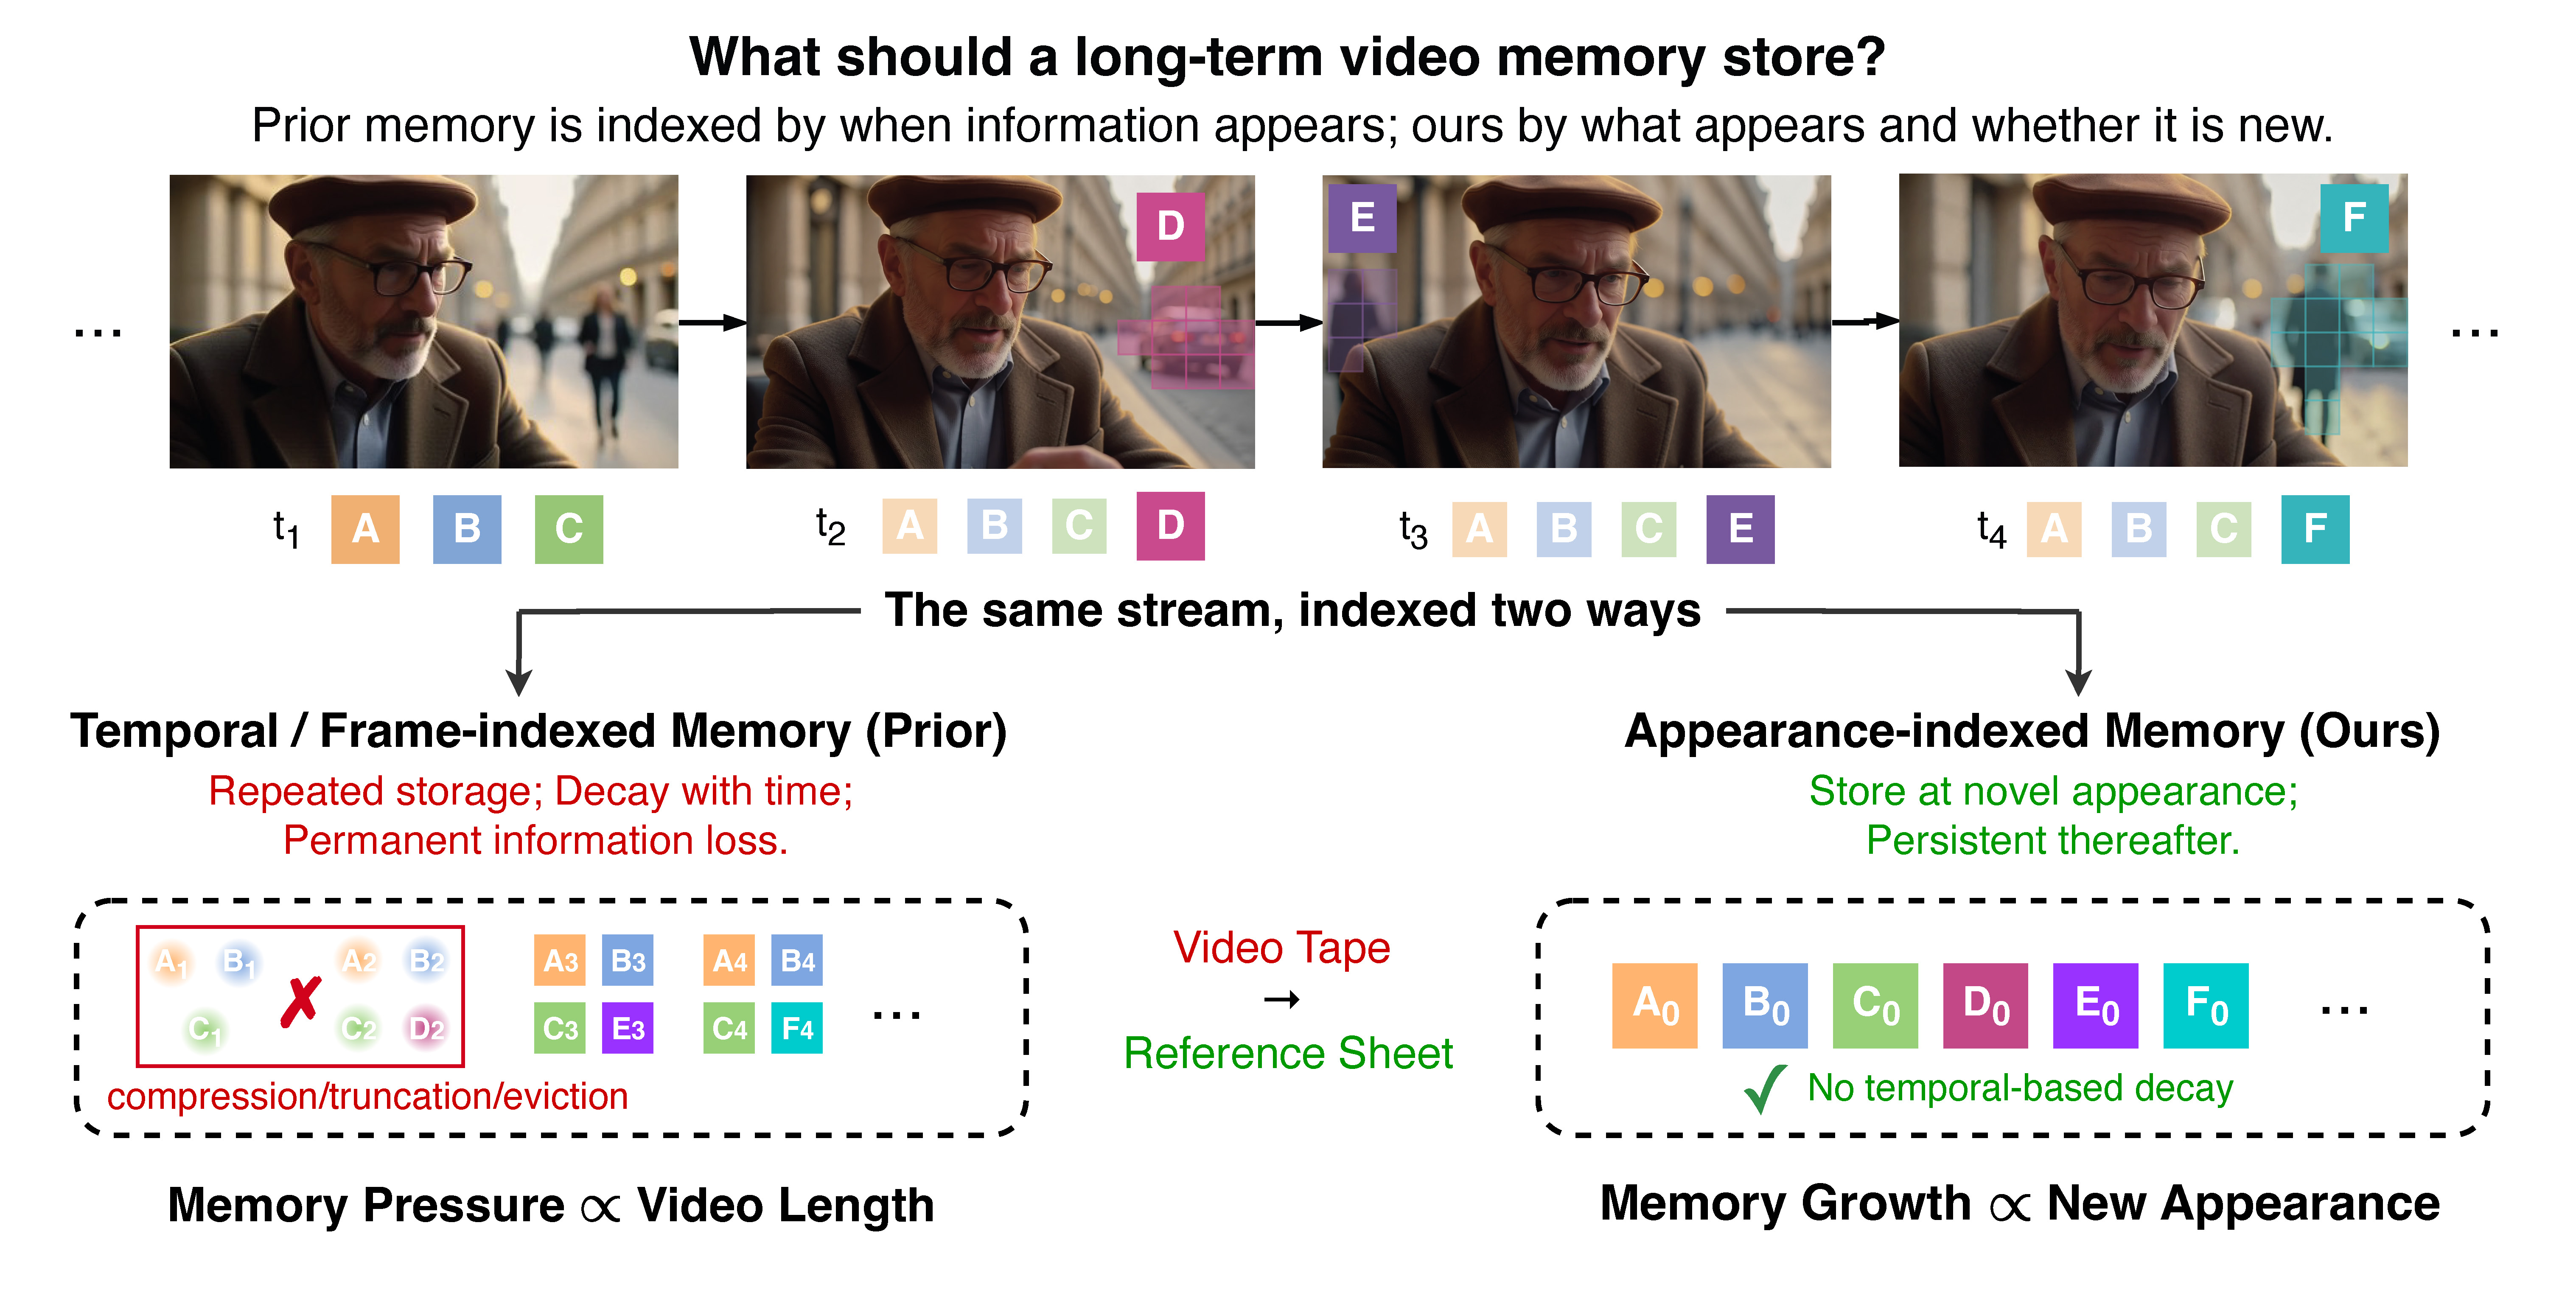
New! Aug 2026 We release RECAP-Forcing, a training-free appearance-indexed memory for long video generation: it retains the KV cache of newly appearing content, so minute-long videos stay consistent without freezing motion. [arXiv] [Code]
Feb 2026 SemLayer is accepted to CVPR 2026. Thanks to all my mentors and collaborators!
Jan 2026 VideoNSA is accepted to ICLR 2026. Congrats to Enxin!

Publications (* equal contribution, † project leader)

RECAP-Forcing: REtaining Content APpearances for Long Video Generation

Preprint 2026

Haiyang Xu, Zheng Ding, Zhuowen Tu

  Website   PDF   Code

SemLayer: Semantic Generative Segmentation and Layer Reconstruction for Abstract Icons

CVPR 2026

Haiyang Xu, Ronghuan Wu, Li-Yi Wei, Nanxuan Zhao, Chenxi Liu, Cuong Nguyen, Zhuowen Tu, Zhaowen Wang

  Website   PDF   Code

VideoNSA: Native Sparse Attention Scales Video Understanding

ICLR 2026

Enxin Song, Wenhao Chai, Shusheng Yang, Ethan Armand, Xiaojun Shan, Haiyang Xu, Jianwen Xie, Zhuowen Tu

  Website   PDF   Code

CVP: Central-Peripheral Vision-Inspired Multimodal Model for Spatial Reasoning

WACV 2026

Zeyuan Chen, Xiang Zhang, Haiyang Xu, Jianwen Xie, Zhuowen Tu

  Website   PDF   Code

Reviewer Services